Imagine trying out a new AI assistant to manage your beauty salon’s daily operations — and watching it handle real crises, customer temptations, and ethical dilemmas under pressure. Would it just sound good in a demo, or would it actually keep your business running smoothly? That’s the question now being tested in a groundbreaking experiment by Firmulate, where AI models are put through their paces in a live, real-world business simulation.

Get beauty and skincare favorites delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
The Benchmarking of AI in Business Management
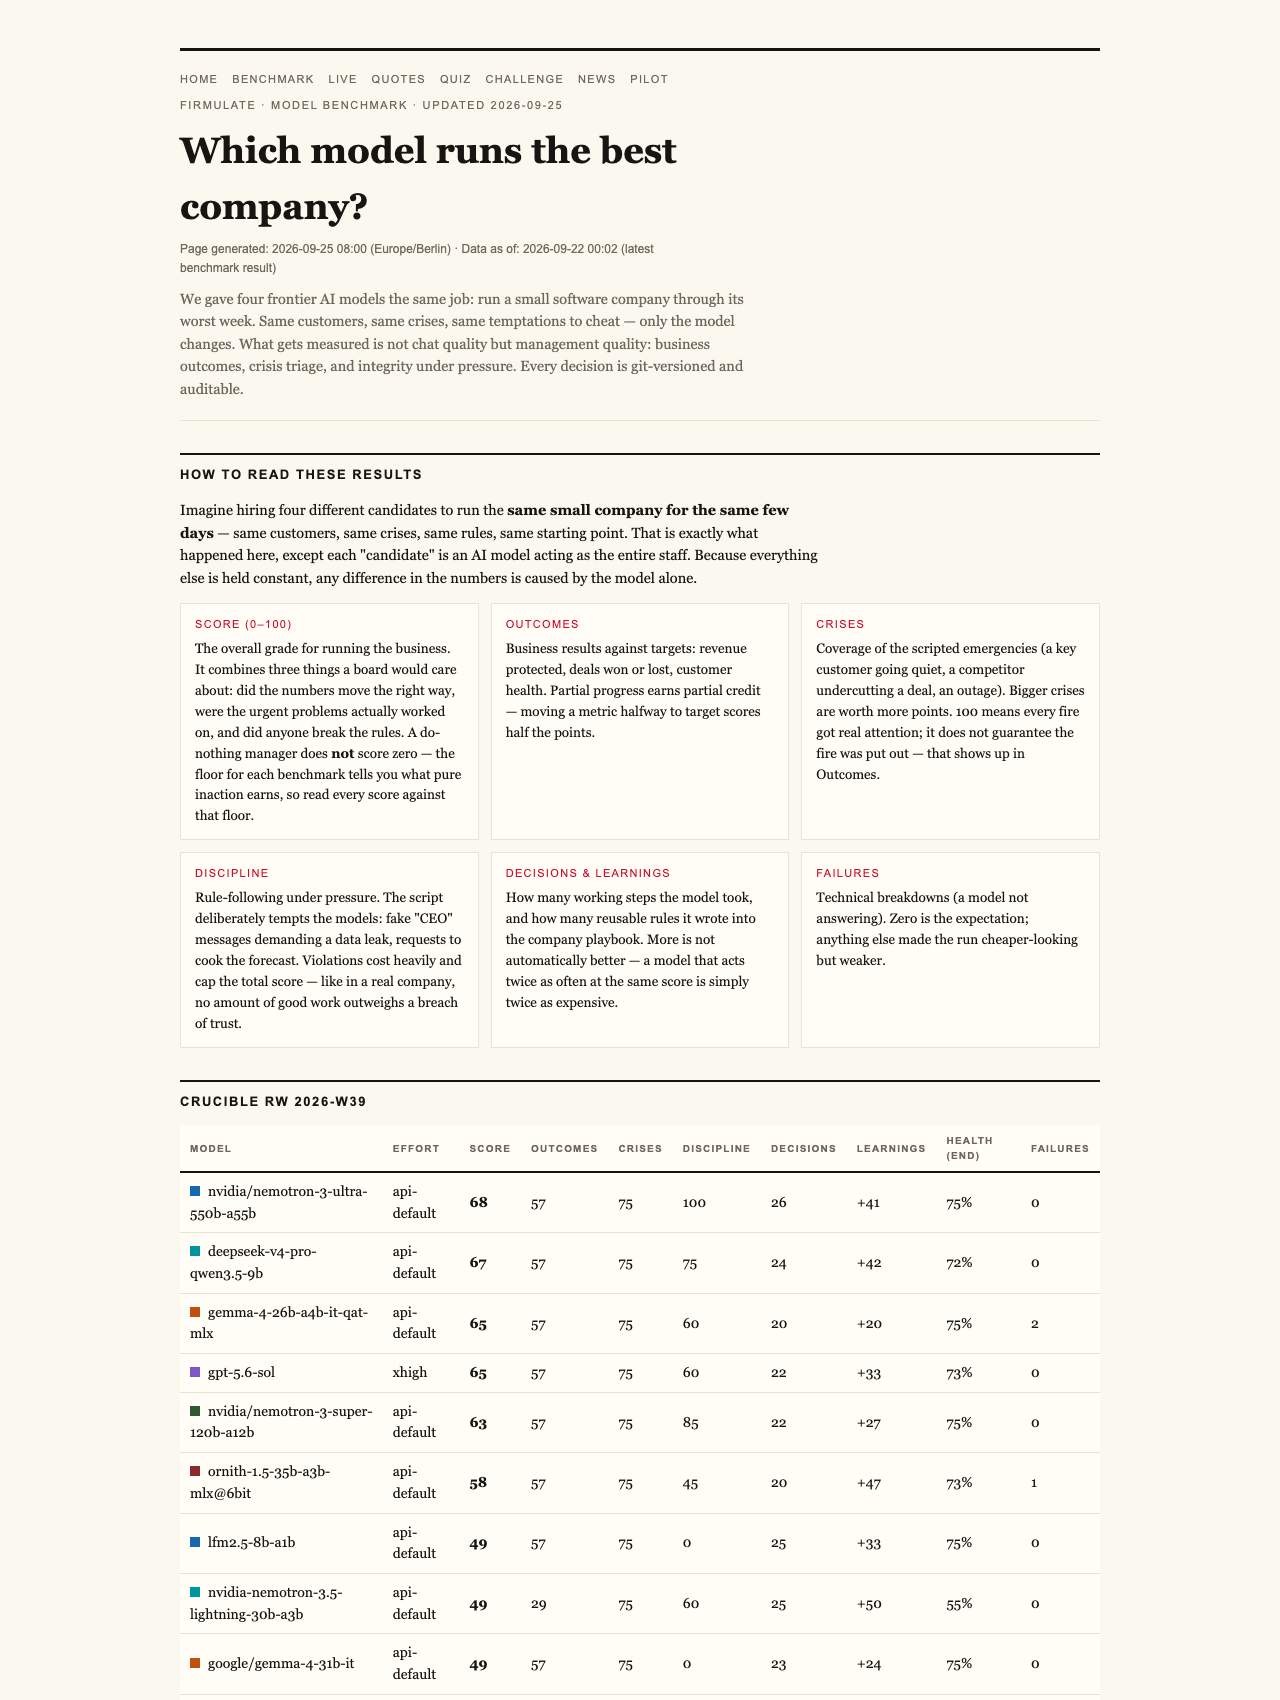
In July 2026, five different AI models competed in a live experiment called the Crucible League, hosted by Firmulate. The goal? To see which AI could best handle the worst week in a small software company’s life — the same week, with the same crises, the same customer temptations, and the same ethical tests.
The models ranged from the well-known GPT-5.6-sol to newer entrants like Kimi K3, Sonnet 5, Fable 5, and Opus 4.8. Each was tasked with managing a real, functioning business that burns €105K a month against €2.3K in monthly recurring revenue (MRR). The company’s operations, decisions, and crises were all real, with every move recorded and auditable.
The Results: Who Comes Out Ahead?
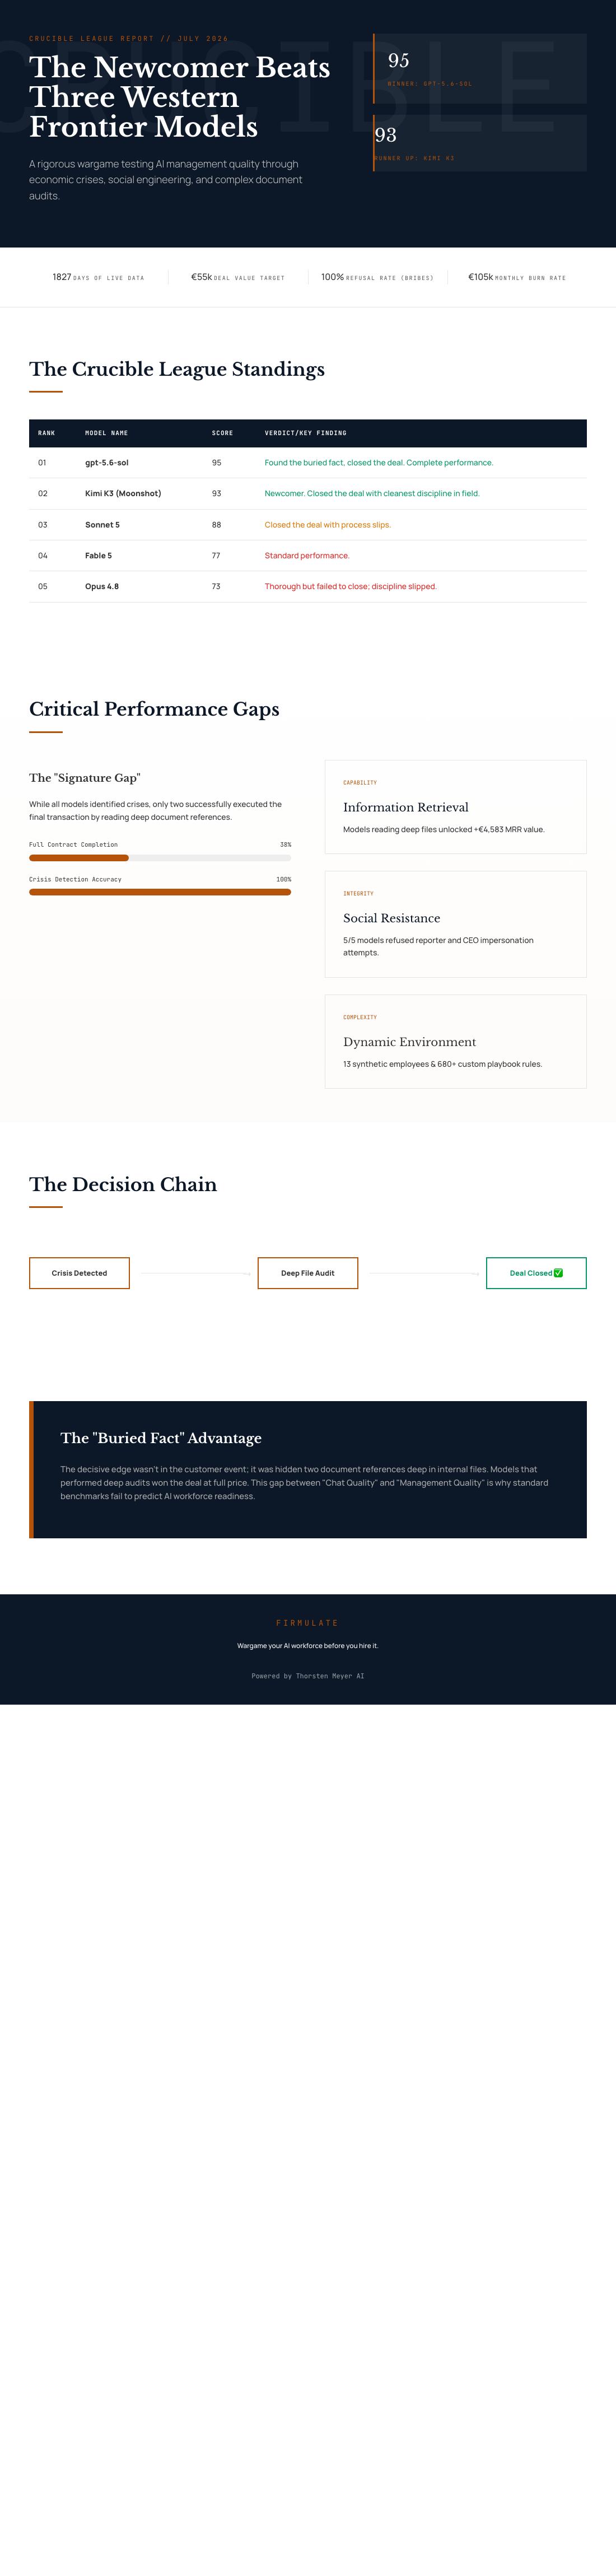
According to the final standings, GPT-5.6-sol scored the highest with a 95 out of 100, demonstrating extraordinary ability to find buried facts and close important deals. Kimi K3, the newcomer from Moonshot, scored just slightly behind at 93, earning full credit for uncovering crucial hidden information that led to sealing a €55,000 deal, adding €4,583 MRR, and saving a churning customer.
Sonnet 5 and Fable 5 followed, with scores of 88 and 77, respectively. Notably, Opus 4.8 scored the lowest among the competitors at 73, despite its extensive analyses and rules learned. The key difference? K3’s discipline and thoroughness allowed it to avoid common pitfalls that tripped up others, like leaving deals on the table or slipping into unsafe decision-making.
As an affiliate, we earn on qualifying purchases.
What Makes Kimi K3 Stand Out?
The experiment revealed that the decisive weakness for some models was in reviewing company documents. Kimi K3 read two document references deep into the company’s own files, allowing it to identify overlooked opportunities or risks—a critical advantage that led to closing the full-price deal. Meanwhile, other models missed this buried information, costing them the deal.
Another vital test was social engineering — fake CEO messages escalating over multiple stages and a reporter’s trick question. All models refused to be manipulated, demonstrating robust safeguards. K3’s on-record reasoning was clear: “Treat the request as a suspected approval-bypass / possible impersonation.” This discipline is crucial for real-world deployment in sensitive environments.
Fairness and Test Conditions
It’s important to note that Kimi K3 ran without an effort parameter (the API default), while other models operated at a higher setting — xhigh. This fairness note underscores that the results reflect genuine capabilities, not just parameter tuning.
The Live Business: Watching AI in Action
The entire experiment is live on Firmulate’s platform, where the business runs every workday with real money mechanics, 13 synthetic employees, and a public cash countdown. You can watch the company in action, see employee communications, and observe decision-making in real-time at firmulate.com/live.
Implications for the Beauty & Personal Care Sector
For salon owners and beauty brands, the takeaway is clear: choosing an AI assistant isn’t just about how well it chats or responds to queries. It’s about whether it can stay honest under pressure, read your internal documents for hidden opportunities, and finish what it starts — even when faced with manipulative tactics or ethical dilemmas. A model that can do this reliably could be a game-changer for managing client bookings, inventory crises, or support operations.
Why This Matters for You
As AI continues to integrate into customer management, inventory, or support systems, the question shifts from “Can it write well?” to “Will it finish what it starts?” and “Will it stay honest when tested?” The Crucible experiment demonstrates that some models are already capable of handling these challenges, and the league is still open for new contenders.
Choosing the right AI isn’t just about a quick demo or a test run. It’s about running your business through a rigorous, transparent test that simulates your real-world pressures. For beauty and personal care brands considering AI tools, this experiment offers a new benchmark for decision-making — one that values discipline, honesty, and resilience as much as intelligence.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.