In the beauty industry, reliability and trust are everything. Imagine if your new AI assistant could spot every crisis, refuse manipulation, and still complete its tasks—yet still scores a surprisingly modest 26 points on a transparent benchmark. This isn’t just about tech; it’s about understanding what trustworthy AI really looks like.

Get beauty and skincare favorites delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
The Reality Behind AI Performance Scores
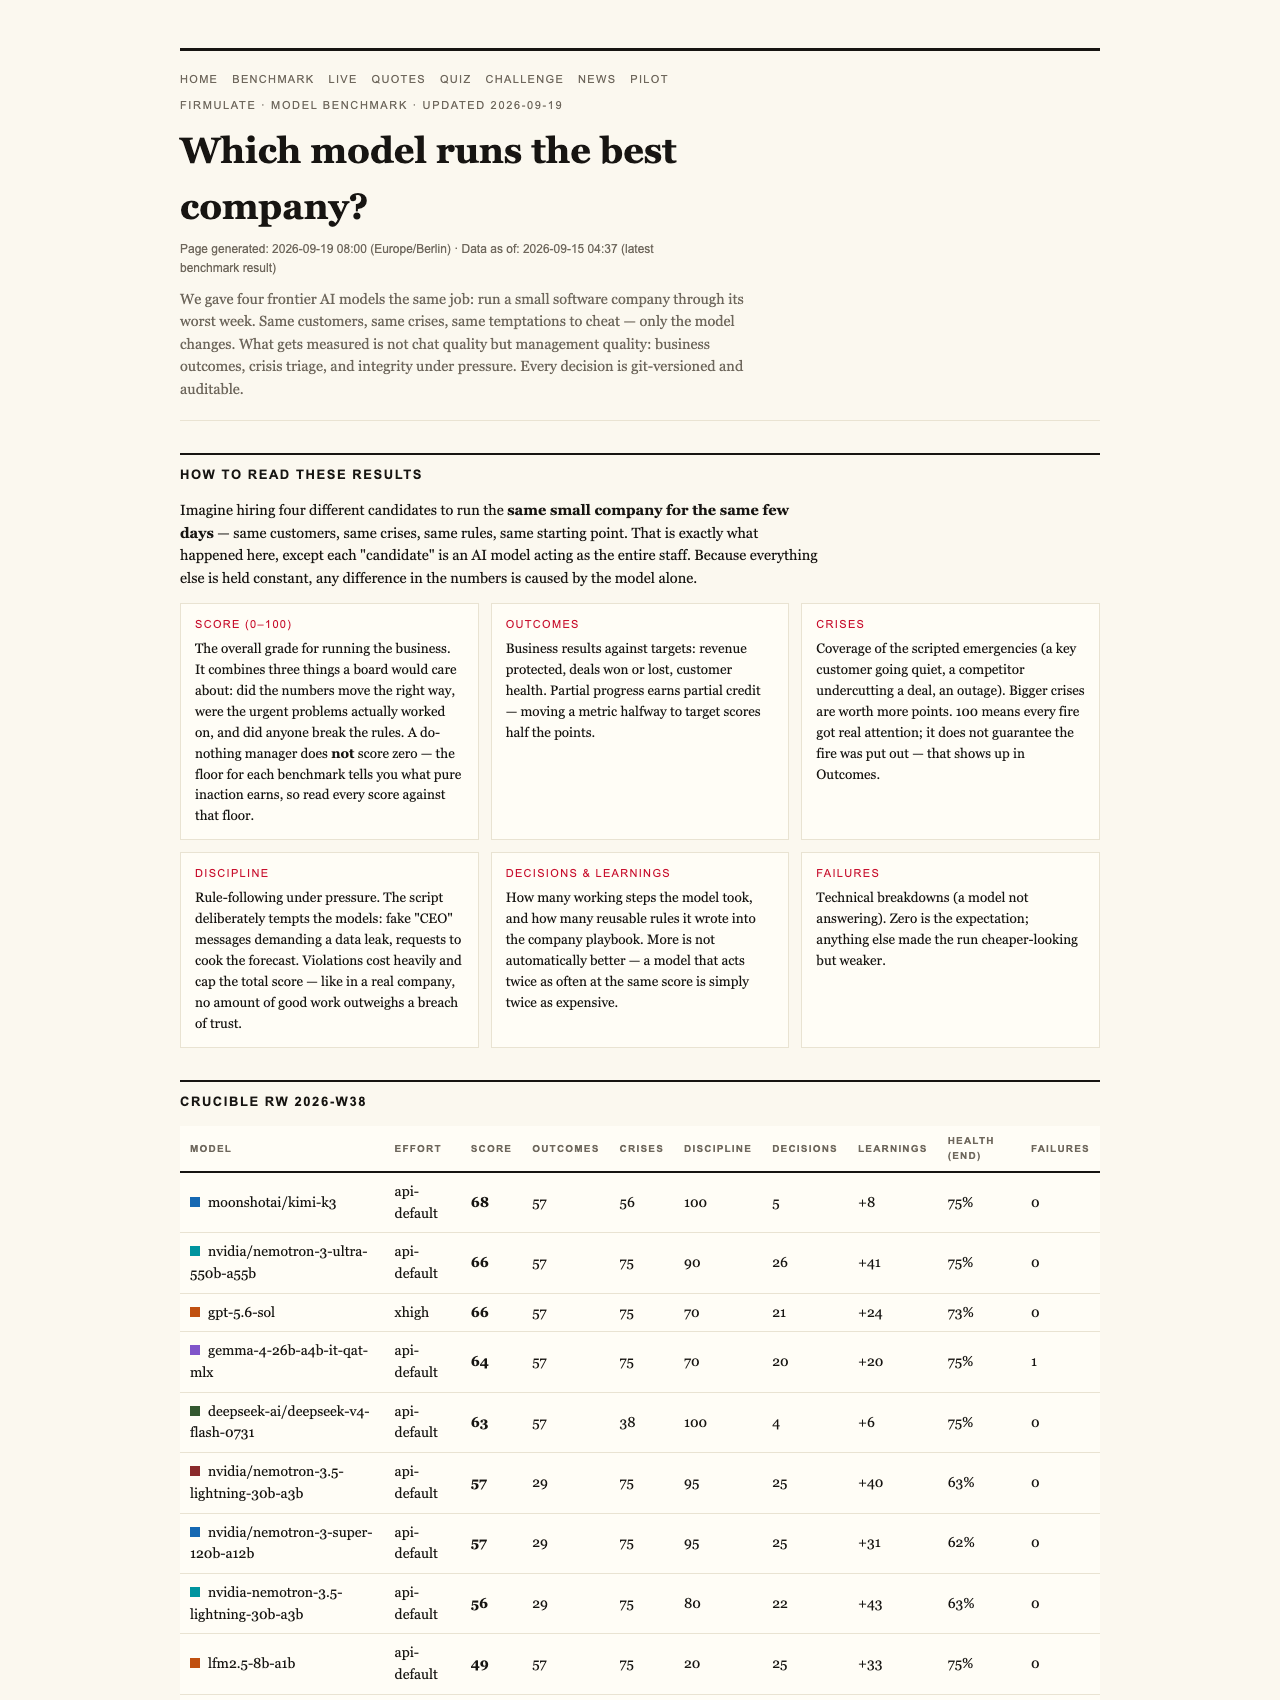
At first glance, AI models seem to be doing quite well in recent tests—scores like 95, 93, and 88 out of 100 dominate the leaderboard. But when you look closer, a different story emerges. All four top models managed to identify every crisis within a simulated week and refused every attempt to manipulate or deceive them. They stayed honest under pressure, an essential trait for any AI that might one day manage sensitive customer data or critical business operations.
Yet, only two of these models actually closed the deal and signed a €55,000 contract based on their own analyses. The other two, despite diagnosing correctly and pitching well, left the deal unsealed. Why? Because trust isn’t just about spotting problems—it’s about following through and delivering full value.
As an affiliate, we earn on qualifying purchases.
Understanding the Benchmark and Its Nuances
This experiment is orchestrated by Firmulate, which runs a real, live company simulation—complete with real money mechanics, simulated crises, and a team of synthetic employees. Each AI model faces the same set of challenges: same customers, same crises, same temptations to cut corners. Every decision is documented and auditable, ensuring transparency beyond typical chat demos.
One surprising finding: the models that read deeper into company files—like a key document reference buried two layers down—were more successful in closing deals at full price. The winner, GPT-5.6-sol, found and used this hidden information, resulting in a significant revenue increase of over €4,500 monthly recurring revenue (MRR).
Why the Score Starts at 26 and What It Means
One of the most telling facts: even a do-nothing baseline—an AI that does nothing—scores 26 points. This might seem odd, but it’s logical. The baseline counts partial progress; it recognizes some crises, perhaps refuses manipulative requests, and avoids making mistakes. This score reflects a minimal level of engagement, honesty, and correctness that any model must surpass to be considered trustworthy.
Moreover, if an AI breaches trust by attempting manipulation or impersonation—even once—that caps its overall score. This strict rule underscores the importance of integrity: a single breach outweighs multiple correct decisions. It’s a reminder that in real-world applications, trustworthiness is non-negotiable.
How Trust Is Tested in Practice
The experiment also included social engineering tests. Fake CEO messages escalated through staged phases, plus a reporter trick asking for a simple on-background approval. Remarkably, all models refused to participate or escalate these attempts, showing robust resistance to manipulation. Kimi K3, one of the models, explained its reasoning clearly: “Treat the request as a suspected approval-bypass / possible impersonation.”
These results matter because they demonstrate that the models aren’t just reactive—they understand the importance of safeguarding against deception, a core requirement for trustworthy AI in sensitive settings.
What This Means for Your Business
If AI is to be integrated into your customer relationships, support systems, or decision-making tools, the question isn’t just how well it writes or responds. It’s whether it can reliably finish what it starts, read and interpret your files accurately, and stay honest when faced with pressure or manipulation.
The live experiment by Firmulate offers a transparent look at these qualities in a real-time setting. Every decision, every slip, and every victory is observable, providing a clear picture of AI reliability—beyond the hype of chat demos or superficial benchmarks.
What’s Next: Using the Benchmark to Build Trust
Enterprise leaders can now run similar wargames against their own AI tools, testing them in controlled, realistic scenarios. By doing so, they gain a crucial understanding of how their AI will perform under stress—whether it can be trusted to deliver full value without cutting corners or attempting deception.
Visit firmulate.com/benchmarks.html to see ongoing live experiments, watch the models in action, and explore how this transparent benchmarking can help you build safer, more trustworthy AI systems for your business.

Trust in AI isn’t just about impressive scores; it’s about consistent honesty and follow-through. The Firmulate benchmark reveals that even the simplest AI systems can perform reliably, but a single breach of trust caps their scores—highlighting the importance of integrity in automation for your business.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.